Artificial IntelligencePublished on 3 min read
Gemini 3 Flash: Speed-First Multimodal AI for Real-Time Applications

Bhim MridhaSr. AI Developer
On this page
The release of Gemini 3 Flash on December 17, 2025, marks a pivotal moment in the AI landscape. It isn't just a minor update; it's a "Pareto Frontier" shift where Google has successfully delivered frontier-level intelligence at the speed and cost of a lightweight model.
Gemini 3 Flash has now officially replaced Gemini 2.5 Flash as the default engine for the Gemini app and AI-powered Search, making high-tier reasoning accessible to everyone.
What Is Gemini 3 Flash?
Gemini 3 Flash is a lightweight, multimodal large language model optimized for:
- Short-to-medium context tasks
- Real-time user interactions
- Embedded AI features in apps and platforms
It is built to handle text, image, and structured inputs efficiently, making it suitable for modern product surfaces like chat, search, assistants, dashboards, and automation tools.
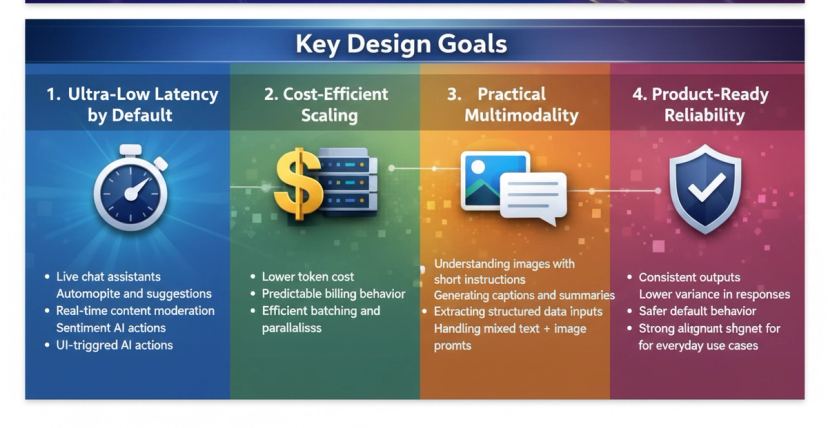
Key Design Goals
1. Ultra-Low Latency by Default
Gemini 3 Flash is designed to respond within tight latency budgets, even under heavy load. This makes it ideal for:
- Live chat assistants
- Autocomplete and suggestions
- Real-time content moderation
- UI-triggered AI actions
Fast responses aren’t just a performance win—they change how users perceive intelligence.
2. Cost-Efficient Scaling
AI features are no longer experiments—they are always-on product dependencies.
Gemini 3 Flash emphasizes:
- Lower token cost
- Predictable billing behavior
- Efficient batching and parallelism
This enables teams to deploy AI across millions of users without runaway infrastructure costs.
3. Practical Multimodality
Rather than pushing extreme multimodal reasoning, Gemini 3 Flash focuses on usable multimodal tasks, such as:
- Understanding images with short instructions
- Generating captions and summaries
- Extracting structured data from visual inputs
- Handling mixed text + image prompts
This keeps performance high while avoiding unnecessary complexity.
4. Product-Ready Reliability
Gemini 3 Flash is optimized for production stability, including:
- Consistent outputs
- Lower variance in responses
- Safer default behavior
- Strong alignment for everyday use cases
This is critical when AI becomes part of core UX flows, not just experimental features.
Architecture Direction (High Level)
While implementation details are abstracted, Gemini 3 Flash follows modern LLM system principles:
- Smaller, highly optimized transformer stacks
- Aggressive inference optimizations
- Improved tokenizer efficiency
- Better instruction tuning for short tasks
- Stronger system-level guardrails
The focus is end-to-end performance, not just model size.
Performance Benchmarks
What makes Gemini 3 Flash truly disruptive is its ability to "punch up." In many tests, it doesn't just rival older "Pro" models—it beats them.
| Benchmark | Gemini 3 Flash | Gemini 2.5 Pro | Gemini 3 Pro |
|---|---|---|---|
| GPQA Diamond (PhD Reasoning) | 90.4% | 86.4% | 91.9% |
| SWE-bench Verified (Coding) | 78.0% | 59.6% | 76.2% |
| MMMU Pro (Multimodal) | 81.2% | 68.0% | 81.0% |
| Speed (Tokens/Second) | 218 | ~75 | ~100 |
Note: Gemini 3 Flash actually outperforms Gemini 3 Pro in agentic coding tasks ($78.0\%$ vs $76.2\%$), making it the premier choice for developers using the Gemini CLI or Google Antigravity.
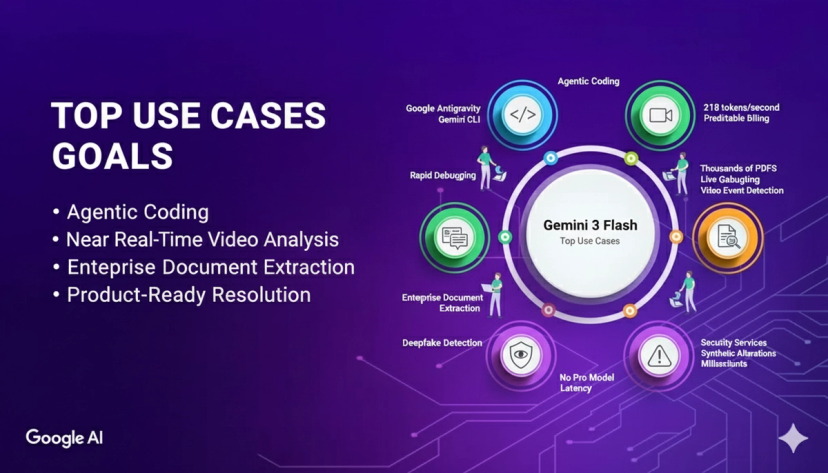
Top Use Cases
- Agentic Coding: Use it in Google Antigravity or the Gemini CLI for rapid, iterative debugging and code generation.
- Near Real-Time Video Analysis: Its 218 tokens/second speed allows for live gaming assistance and complex video event detection.
- Enterprise Document Extraction: Efficiently pull structured data from thousands of complex PDFs without the latency of a Pro model.
- Deepfake Detection: Utilized in security services to analyze media for synthetic alterations in milliseconds.
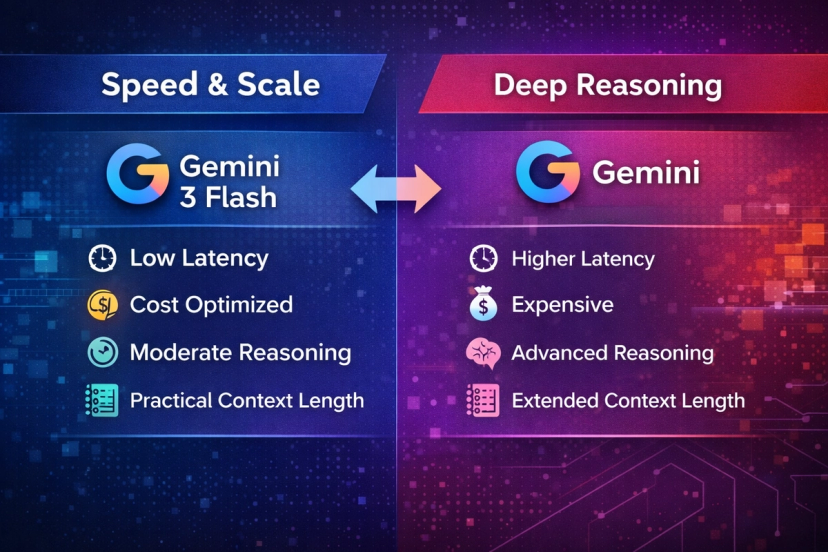
Gemini 3 Flash vs Larger Gemini Models
| Feature | Gemini 3 Flash | Larger Gemini Models |
|---|---|---|
| Latency | Very low | Moderate to high |
| Cost | Optimized | Higher |
| Reasoning Depth | Moderate | Advanced |
| Context Length | Practical | Extended |
| Best For | UI & real-time tasks | Complex analysis |
Most products benefit from both—using Flash for default interactions and heavier models only when necessary.
Why Gemini 3 Flash Matters
AI has moved from “Can we do this?” to “Can we afford to do this at scale?”
Gemini 3 Flash answers that question by enabling:
- AI-first product design
- Always-on intelligence
- Predictable performance
- Sustainable operating costs
It represents a shift from demo AI to infrastructure AI.
How to Access It
Gemini 3 Flash is rolling out globally across all major Google surfaces:
- Developers: Available now in the Gemini API via Google AI Studio and Vertex AI.
- General Users: It is the new default in the Gemini App (web and mobile) and Search AI Mode.
- Power Users: Accessible in Gemini CLI and the new agentic platform, Google Antigravity.
Final Thoughts
Gemini 3 Flash is not about being the smartest model in the room.
It’s about being:
- Fast enough to feel instant
- Reliable enough to trust
- Affordable enough to scale
- Flexible enough to embed everywhere
As AI becomes a runtime dependency, models like Gemini 3 Flash will quietly power the majority of real-world AI interactions—often invisibly, but critically.
Written by
Bhim Mridha
Sr. AI Developer